Author Archives: Jason Green

Putting College Back Together Again

Today I stumbled across a thought-provoking post from Kyle Saunders of Colorado State University. In it he proposes that changes in the job market, driven in part but not completely by AI, are creating a choice for institutions between offering the traditional four year on campus model that Saunders calls Elite Mentorship, and an accelerated competency focused degree which he labels a Credential Factory. These two paths create graduates with very different experiences and skill sets.

Disclaimer — part one: Although I don’t currently work in higher ed, I spent more than two decades working in the sector after growing up a faculty kid at a public regional. I have four degrees, a bachelors and three masters. My last masters was employability driven and I completed it in 16 months, not quite a speedrun (to borrow Saunders’s term) but focused on efficiency rather than the experience.

Saunders points out that many employers don’t seem to be making a distinction between the two sorts of college experiences and treat the resulting credentials as equivalent. In doing so they undermine what he calls the formation layer, that experience of being guided over an intellectual hurdle during a faculty office hour or talking through a complex question in a class discussion or late at night in a residence hall lounge. It is this formation layer and wanting to be a part of creating it for others that drew many people , myself included, into higher education as a career. What happens when those paying the bills, either governments, parents, or employers (in the form of better paying and more secure jobs for college graduates) don’t actually value the formation layer. Instead, they value the sorting, taking the fact that you gained admission to and then completed a degree at ________ University as evidence of something. If the formation layer is truly important, we as a society would put a lot more effort into measuring it.

For all the think pieces about trust and value/ return on investment, maybe this is a key to understanding higher education’s current challenge. Perhaps for a long time, only a small proportion of stakeholders have prioritized the formation layer. but colleges have been able to “bundle” this with the things stakeholders care about like employable skills in the same way that general education requirements bundle low demand subjects like art and philosophy with higher demand majors. Now, just as subjects like foreign languages are shed from the curriculum in the name of efficiency, intellectually transformative experiences are dropped in favor of skills that can be quickly developed and demonstrated, in the name of efficiency.

Disclaimer — part two: I was a music and French major and then a music and French graduate student. It hurts every time I read about a music or foreign language department being sacrificed, and that seems to happen quite regularly these days.

Where does this leave room for intellectual transformation? Counterintuitively, AI may be a great opportunity. Now that your LLM of choice can create a perfectly serviceable email or presentation slide deck, the differentiator of the well educated is the ability to do deep and thoughtful analysis, the sort of thing the formation layer helps you learn to do. If we can measure that (admittedly no easy task) and convince employers that it’s worth hiring for (a perhaps even less easy task), there may be a way to put at least some of the bundle back together.
On Netizenship

Yesterday I saw a post from Ben Werdmuller that sent me down a bit of a rabbit hole on the future of the open web.  Anil Dash presents a grim prognosis for the open web. Julien Genestoux points out that we ended up here by repeatedly choosing convenient and cheap (free) instead of open and portable.  He concludes with the idea that, “The web needs netizens again.” To his credit, he lists out some specific ideas on what that looks like.  Ben notes that ,as much as openness advocates don’t like to talk about funding, “If people are going to build good things, they need to be able to eat and pay rent so they can keep doing it.” All of this has me thinking.  What are the barriers to this sort of future and how might we  overcome them.  Julien points out that people pay as much for a streaming service every month as they would to support an open platform.


I’m thinking for the moment particularly about the social space. The trajectories of Activitypub and ATProto tell a difficult to hear story.  Friction is really important.  Even though Mastodon has been around much longer, Bluesky has almost three times the total number of users. My best guess is that this comes down to a trust issue.  Unless you know someone who runs a mastodon server, you’ll probably choose one of the biggest sites. To this point, ATProto alternatives to Bluesky are limited.  With size and hopefully stability come infrastructure demands.  Even without a need for ROI (Bluesky has taken VC money), there are bills to be paid and we’re right back at Ben’s questions about funding. Ideally the social networking space would be very decentralized.  I imagine the typical server as having a dozen users. Servers would be as populous as a city block.  


There is another option, of course.  You can do it yourself. I run a home server, so this approach must appeal to me.  However, while I briefly experimented with running Mastodon on a VPS, I abandoned DIY social networking. I did so because I wasn’t confident in my ability to be my own CISO, and I was concerned about the ramifications of people I might not know sending content to my server. Is there something we can do to lower the barrier to entry?


I also saw Dave Winer’s post suggesting that we just do this all with RSS. A chat could just be a subscription to a set of RSS feeds.  I’ve thought about using something like River to aggregate my Bluesky and Mastodon timelines.  The problem is there’s no easy way in RSS to reply to posts.  We feel close to and yet far from the point where your social network could live on your own device.

Photo Editing

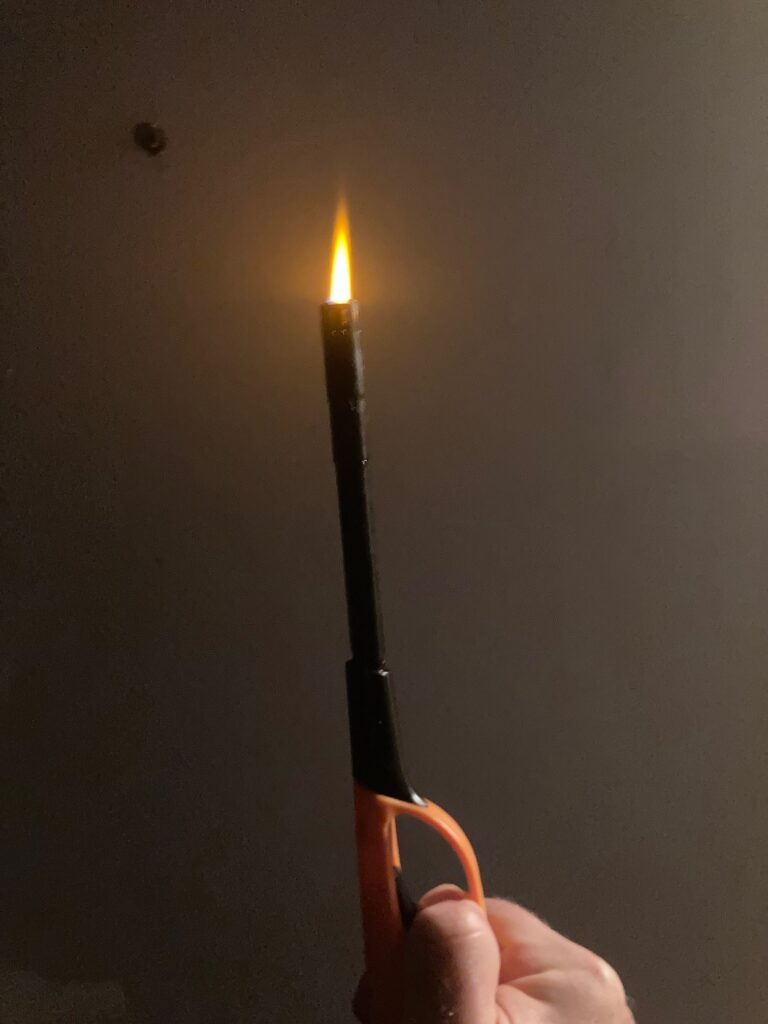
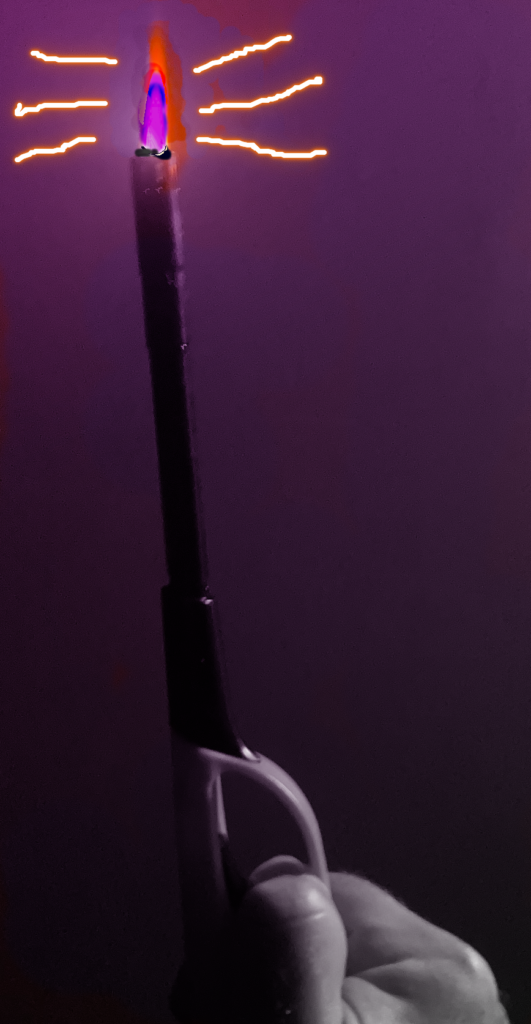
First the before and after

Before
After

Editing Process

Because I took the photo one handed and was holding the lighter in my other hand, I didn’t have much opportunity to compose the shot, so the first thing I did was crop. Then I desaturated everything but the flame with the sponge tool so the rest of the image would be black and white.

Next I used the color change brush to change the flame from the original yellow to fuchsia, to make it look eerie (it is almost Halloween after all) and applied a soft color fuchsia gradient to create the illusion that the flame was shining fuchsia light on the background. I pulled the gradient on a diagonal so the strongest area would be near the candle flame Finally I added orange neon pen strokes that match the orange flame edge. To make it look more artistic and less photographic, I freehanded the tools rather than use a mask.

The gradient tool was the most difficult to work with, because there were so many options. Thankfully, the multiple levels of undo made it easy to experiment and backtrack if something didn’t work out. I tried a couple of other images before I settled on this one, but they were too monochromatic for the color changes to have the impact I wanted.

I liked Pixlr E more than I thought I would, as the lightweight interface helped me be less intimidated than I am with the GIMP or Photoshop. Although I didn’t use any AI components that I’m aware of, their presence makes me unlikely to use Pixlr again. I fully expect that a careful reading of the terms of service would reveal that everything users upload is used for AI training data, and I very much don’t want to participate in feeding that machine.

The stylesheet goes external

This fortnight we were to create a resumé. The key change from previous assignments: the style sheet was now to be a separate document linked to the HTML file via link rel=”stylesheet” in the document head. This is of course the way most style sheets work, and I felt as if I were at last doing something I might do on a “real” web project.

My CSS is rusty and I did have several problems. The list of required style components made it harder to create a visually cohesive document. I would have left several things out if not for the assignment directions, including colored text and definitely the photo.

From a technical standpoint , the instruction to use <p></p> tags made for lots of white space, since most browsers add a blank line after each </p> I considered experimenting with unordered list elements and there is, it turns out a list-style-type: none attribute. I ended up not bothering, since the presence of the colored heading text and the photo made this a resumé I wasn’t going to re-use outside the class context.

The aesthetic challenge I decided to tackle was column width. Because the text lines were short, there was even more white space on the right hand side of the page. I “fixed” this by using nested <div>’s to create a two column layout, which made the page better balanced. The key attribute here is that you can make left: have a value of float rather than a set margin value. Using this I was able to put the second column next to the first. I could have used a <div> to make my heading wrap around the image, which was at the top left of the document, but I ended up brute forcing it by using negative top: values on elements that ended up in the header (top section- not <head> ) of the page. Columns via nested <div>’s was something I hadn’t done before.

I’m pondering how to move forward with an actual small website project I have to complete by the end of the year. I had planned to use a static site generator, but wonder if the relearning curve for CSS would be less than learning the new software. The problem is I don’t remember enough JavaScript to do things like menus that drop down onmouseover: which I’d really like to have. I need to decide soon.

Starting With CSS

This project was an invitation, intended to make us use the CSS box model. The assignment used an in-line style sheet rather than an external one. In completing the project I had two problems. The constraint of an inline style sheet wasn’t a good fit for the assignment and I had challenges dealing with the border attribute of the box model.

Web designers will debate forever how to decide which projects can use style attributes attached to content elements, which need inline style directives, and which are “big enough” to justify external style sheets. It seems obvious that multi-page sites need external style sheets, so one can apply the same styles to multiple pages. This brings us to the single web page and whether to use an inline sheet, or styles attached to each element.

The benefits of inline style sheets emerge when styles are reused in a document. Rather than copying the style attribute over and over again, the designer can change it once. Unfortunately, this was not that kind of document. It was short and had minimal reuse of styles. Style attributes on individual elements would have been adequate to the task. Perhaps it’s a bit much to call this a problem, since the parameters were driven by the assignment learning outcomes rather than the needs of the particular design task.

My second problem was all about borders. The W3C sandbox to which we were referred showed a nice green border. When I modeled my style sheet on that example — no border. Since we were restricted to a nearly featureless text editor, I wasted time looking for missing punctuation and unclosed tags. That was not the problem.

Like most web designers it was off to search engines. It turns out that there is a border-style attribute included in the box model, but not shown in the W3Schools sandbox. The default value for border-style is “none”. When I added a border-style=solid attribute to my div style declaration, voila , a border. I was reminded that even normally trustworthy sites can have glitches.

Returning to HTML Coding

This week I had an assignment to hand code a minimal personal web page, Including a heading, picture and some formatting. It reminded me a lot of the personal web pages I hand coded in the mid 1990’s. While I understand the benefit of knowing what the HTML “under the hood” actually does, the experience was…..frustrating.

My difficulties included being careless about closing quotes on attributes, and having to do lots of page reloads to get things like image borders the way I wanted them.I resolved them the same way I did in the 1990’s, by saving and reloading in the web browser frequently. This was frustrating because it’s not 1995 anymore and there are better ways. Even a basic IDE with auto-complete would make sure all the brackets and quotes were paired, and a cascading style sheet would make formatting changes easier to manage. I also had to cope with the changes between HTML 4 (in the 1990’s) and HTML 5. I ended up having to look up more attributes than I expected. Things that used to be separate attributes (font-color, text-align, etc.) are now all varieties of the style attribute for example.

What did I learn? First of all, that I now appreciate user friendly interfaces at which I used to scoff, When you’re young, you do things the hard way because it shows off your expertise. As you get older you discover you have better things to do with your time. I’m also beginning to suspect that going tag by tag and attribute by attribute may not be a good match for even small real world web projects. I think hand coding is better for tweaking a website than building a website. Hand coding a web page is like driving a manual transmission car. While there was a time when doing that was necessary, that time has passed, and those who still drive stick shift or hand code HTML do it for very granular control. For most people it’s not worth the trouble.

On Accessibility

Accessibility was unfortunately not a primary consideration of most early web design.  This is perhaps ironic, as the one of Berners-Lee’s design principles in creating HTML was that information was that things were to be tagged semantically (<em> and <strong> ) rather than styled (<b> and <i>). Semantic markup allows browsers to  display material in a way appropriate to the limitations of software and hardware or according to user preference.  For example, a browser designed for a monochrome monitor would choose some formatting other than color to indicate hyperlinks. The rejection of Berners-Lee’s semantic markup perhaps reached its apex with the introduction of the infamous <blink> tag in the mid 1990’s. Not surprisingly, although standard bodies such as W3C have created guidelines, much of the improvement in web accessibility has been driven by government regulation of both government websites and those produced by entities receiving government funding. 

While accessibility is an ongoing process, there are a few aspects that should be a high priority , because of their frequency in web design:

ALT-Text – Since NCSA Mozilla, the web has been a visual medium.  A page filled with only text comes across as quaint and even retro.  However, this means that images need text descriptions.  The HTML standard addresses this with the <img> tag alt attribute, if designers take the time to use it. See below for a site with do’s and don’ts for writing good ALT text.

Color choices – There are many ways to combine colors on a web page. Some of them are not effective. Beyond the difficulty caused by low contrast pairings (such as a pale pastel on white), there are five different kinds of color vision deficiency (see Resources below). Put that all together and you have several ways you can make your site difficult for some of your users to read.

Transcripts / captions – If your web site includes audio and/or video, transcripts and/or captions are important for any users who might have a hearing disability.  The general advice to write a script is helpful, as this should end up being very close to your transcript.  Auto-captioning/ transcripting is improving, but you still need to review and correct the output before adding it to your media.

Resources

  • Guidance on Web Accessibility and the ADA
  • WAVE
    • htttp://wave.webaim.org
    • This suite of tools, from Utah State University , helps web designers test for accessibility.

Reintroducing Myself

Since January, I’ve been enrolled in the M.Ed program in Educational Technology at the University of Arkansas. As is not uncommon with such programs, I’m being asked to blog as a course requirement. It feels a bit odd to write the 500 word bio, since this is actually the third iteration of my personal blog. When you put them all together, they run to just over 250 posts and 19 years. For those 19+ years, I’ve been involve52103d in educational technology in some capacity. Almost all of that involvement was at the two-year college level.

While there is some tendency to think of blogs and the things that grew from them (podcasts, email newsletters, substacks, etc.) as a broadcast platform, I’ve always leaned more toward the “outboard brain” model (Doctorow, 2002) It says something about the transience of all the ed tech we’re busily doing that I had to pull that link from the Internet Archive Wayback Machine, but I suppose we can’t all be Ea-Nasir.

It’s probably also a tell that I’ve named this blog in hypothetical West-Saxon (explanation here – It does have the advantage that a search using the actual blog title will find it, even amongst all the AI) and I labeled my various attempts at web based bookmarking Πίνακες, after the lost catalog of the (also lost) Library of Alexandria. This has something to do with wanting to understand all of this new stuff as part of a long tradition of organizing, preserving, and disseminating knowledge.

Part of the rubric for this post expects something about purpose and topics to be discussed. In the short term, topics to be discussed will derive from course blog assignments. I’ll use a category so those who need to can find them. My non required posts tend to focus on two broad questions:

  • How can technology allow learners to shape their own learning?
  • To what ends aspires this whole education enterprise and how does the availability of various technology shape those ends?

Identity After the Blue Check

This week’s implosion of Twitter has set off an unprecedented migration to alternatives, particularly the ActivityPub based Fediverse. Since that implosion included a complete breakdown of  the verification system (What do blue checks mean today? What will they mean tomorrow?) lots of people started off thinking about identity and impersonation in a decentralized space.

The previous verification system at Twitter was the kind of centralized approach most of us are used to.  Twitter publicly attested the identities of about 400000 accounts belonging to institutions, brands, and various celebrities in the same way most people in the developed world rely on an ID card issued by a government.  To think about how to build an identity system without a central authority, we have to look backwards. Before national ID cards, identity was largely managed through social connections.  You were introduced to someone, in person, by a common acquaintance whom you both trust.  That introduction attests your identities to each other.  This is in essence the web of trust that Pretty Good Privacy tried to build via key-signing.

Of course, the process becomes more complicated when you aren’t in person.  What if that letter of introduction is a forgery?   Oddly, existing social media platforms worked on the electronic version of this problem in a roundabout way, with photo tagging.  When I take a picture of someone and tag them when I post it.  I’m attesting that the account I tagged belongs to the person whose image I posted.  If you also recognize that person’s image, you can take that tag as evidence that a particular account belongs to a particular person.

In the Fediverse, such identity verification as there is relies on having control of some other website.  Mastodon, the most popular ActivityPub implementation, allows you to place a link to your profile with a rel=”me” attribute on your website,  When you add the address of that page to your profile, it appears with a green check.  What this actually does is show that the same entity controls the website and the Mastodon account.

If you control a domain, you have another option, creating a Fediverse server within that domain.  Since you control the domain, you control the Fediverse server. This method is an option for institutions as well as individuals.  mastodon.archive.org  has been launched by the Internet Archive and only IA employees are allowed to have accounts on this instance.  Effectively, IA is publicly attesting the identity of the person attached to each of those accounts. It will be interesting to see if other institutions follow suit.

More Thoughts on the Fediverse

As the on again off again acquisition of Twitter went on again, focus turned back to mastodon, a federated alternative.  As another wave of users dip their toes in the waters, I wanted to share some thoughts.

Scale

The fediverse is predicated on replacing a single site having one set of policies with a network of sites.This is both technically resilient and resistant to the whims of a single owner. There are, however, different ways to realize this concept.

The web interface of mastodon includes a local timeline, A separate local timeline makes sense when each instance is a distinct community. Initially, standing up and administering a server was not for everyone. Mastodon was designed with an administrator role and those administrators are empowered to set policies on their instances. The model here is a collection of “small towns” each with its own culture.

But then something happened — mastodon became popular and more accessible server models became available, including pre- configured VPS’s and hosted options. This opened a new use case, that of the single user instance.  Here, the local timeline becomes unimportant.  This is more like Twitter, which doesn’t have such a thing.  The official iOS Mastodon client has gone as far as not  even showing the local timeline. We have an interesting scenario in which not only policies and standards but also what it means to moderate vary from instance to instance.

Mastodon and protocols 

Mastodon runs on ActivityPub, the under the hood protocol that allows instances to communicate with each other.  It also supports publishing RSS and Atom feeds.  There are other applications that support ActivityPub. For example, A WordPress site can, with the right plugin, publish an Activitypub stream.  This allows a mastodon user to follow that site as if it were a mastodon user. However, that WordPress plugin generates ActivityPub but doesn’t parse it, meaning if you reply in Mastodon, nobody will see it. You end up with different apps using the same protocol to different ends.  Combine this with RSS support and you need to think about your data flows.

Update: Because of incompatibilities with other plugins, I did not test this on my own site. The WordPress site I followed to test was using a custom configuration that I mistook for a default setting.